Own your intelligence · Discover together
Somewhere, in a lab you have never heard of, someone is working on the other half of your breakthrough.
Your Sapience grows from your work and stays with you across AIs. Share what you choose, with your name attached. Sapience is a shared intelligence for humanity, so people and AI can discover what none of us could alone.
iTom shares two notes from his work in Claude Code.
iiMaria accepts, in ChatGPT.
iiiHer AI answers from his notes, with his name on them.
ivHe can withdraw them.
Stored on our servers, on an encrypted disk. Making it unreadable even to us is our top priority. What stays yours
You can use Sapience on your own. Free during beta, with a usage budget per person.
Ask it yourself. It answers from the notes on this map and lights the ones it used.
live map · an example Sapience
Fig. I · the discovery loop. Two people’s loops meet at the record.
Sharing and introductions
A chosen connection starts when you invite a colleague into a shared project. Sapience keeps your AIs in sync.
A found connection is made when your record and a stranger’s contain two complementary contributions to one problem and both of you would benefit from an introduction. Sapience finds complementary work for your problem and introduces the people behind it. Both people accept before anything is shared.
Because knowledge stays owned and credited, Sapience matches it across people and organizations no single vendor could connect. When you choose, what you establish reaches a stranger working on a complementary part of the discovery you are working toward, credited to you, in time to be useful.
Glaciologists needed to sense the whole submerged front of a Greenland glacier. Engineering had the method, distributed fibre-optic sensing, eight years earlier, with no citation path between the fields; by similarity it ranked 22,746th. Sapience re-found the pairing among the first hundred it put forward. The glaciologists made the connection by hand in the end, so this is a connection recovered, not a discovery claimed.
In an internal benchmark on discoveries published after the reasoning model’s training cutoff, Sapience ranked the approach that later won first in 11 of 13 problems, on a small internal set whose protocol we share with partners.
Watch three strangers solve one problem › · Ask Sapience a question
Results
Figures I the discovery loop · II how it connects · III remembers at scale · IV stays current · V works across models · VI learns without forgetting · VII to IX the method · X to XIII the app, recorded at phone size
Remembers at scale
Accuracy holds from 4K tokens to a billion tokens of stored history, with the model reading a few hundred tokens per answer.
Scope BABILong qa3, 4K to one billion tokens of stored history. The official cells run to 10M; 30M to 1B use our corpora with repeating PG-19 book filler.
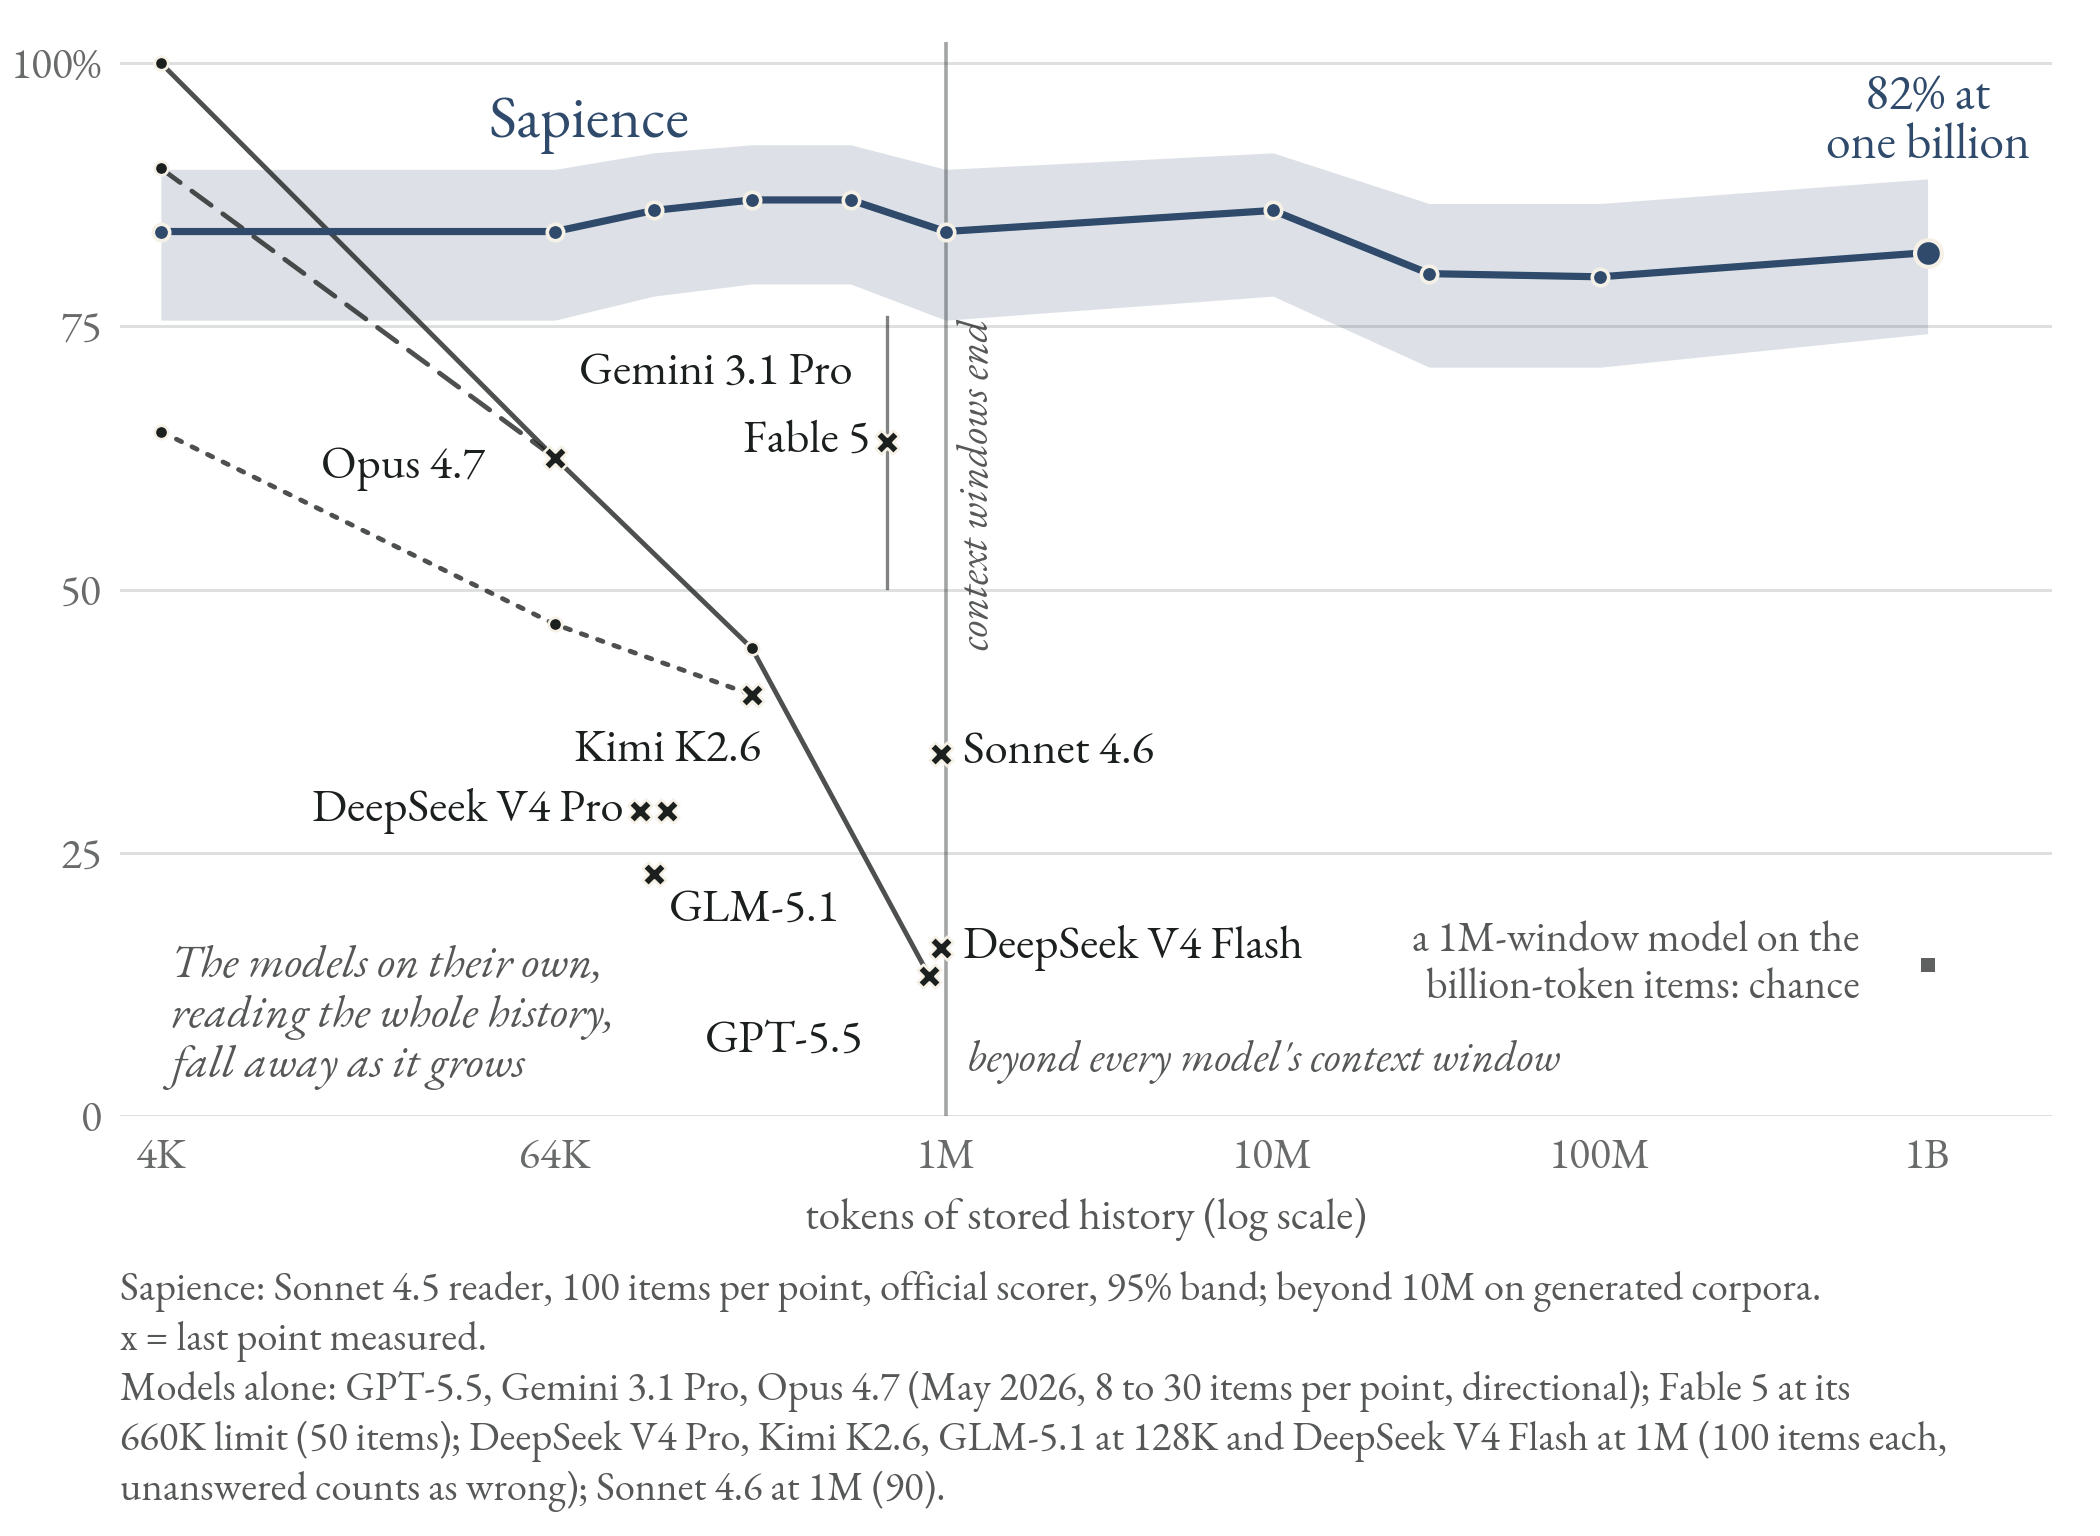
BABILong qa3. The official cells run to 10M; 30M to 1B use our corpora with repeating PG-19 book filler.
Stays current
Asked what a setting is now in a codebase that keeps changing, Sapience answers 88 percent right on the shipped engine, against 48 for Mem0 and 27 for the same model with git grep, on the same 60 questions.
Scope The same 60 questions on the real git histories of Django, LiteLLM, huggingface_hub and vllm, answers graded against git, no AI judge.
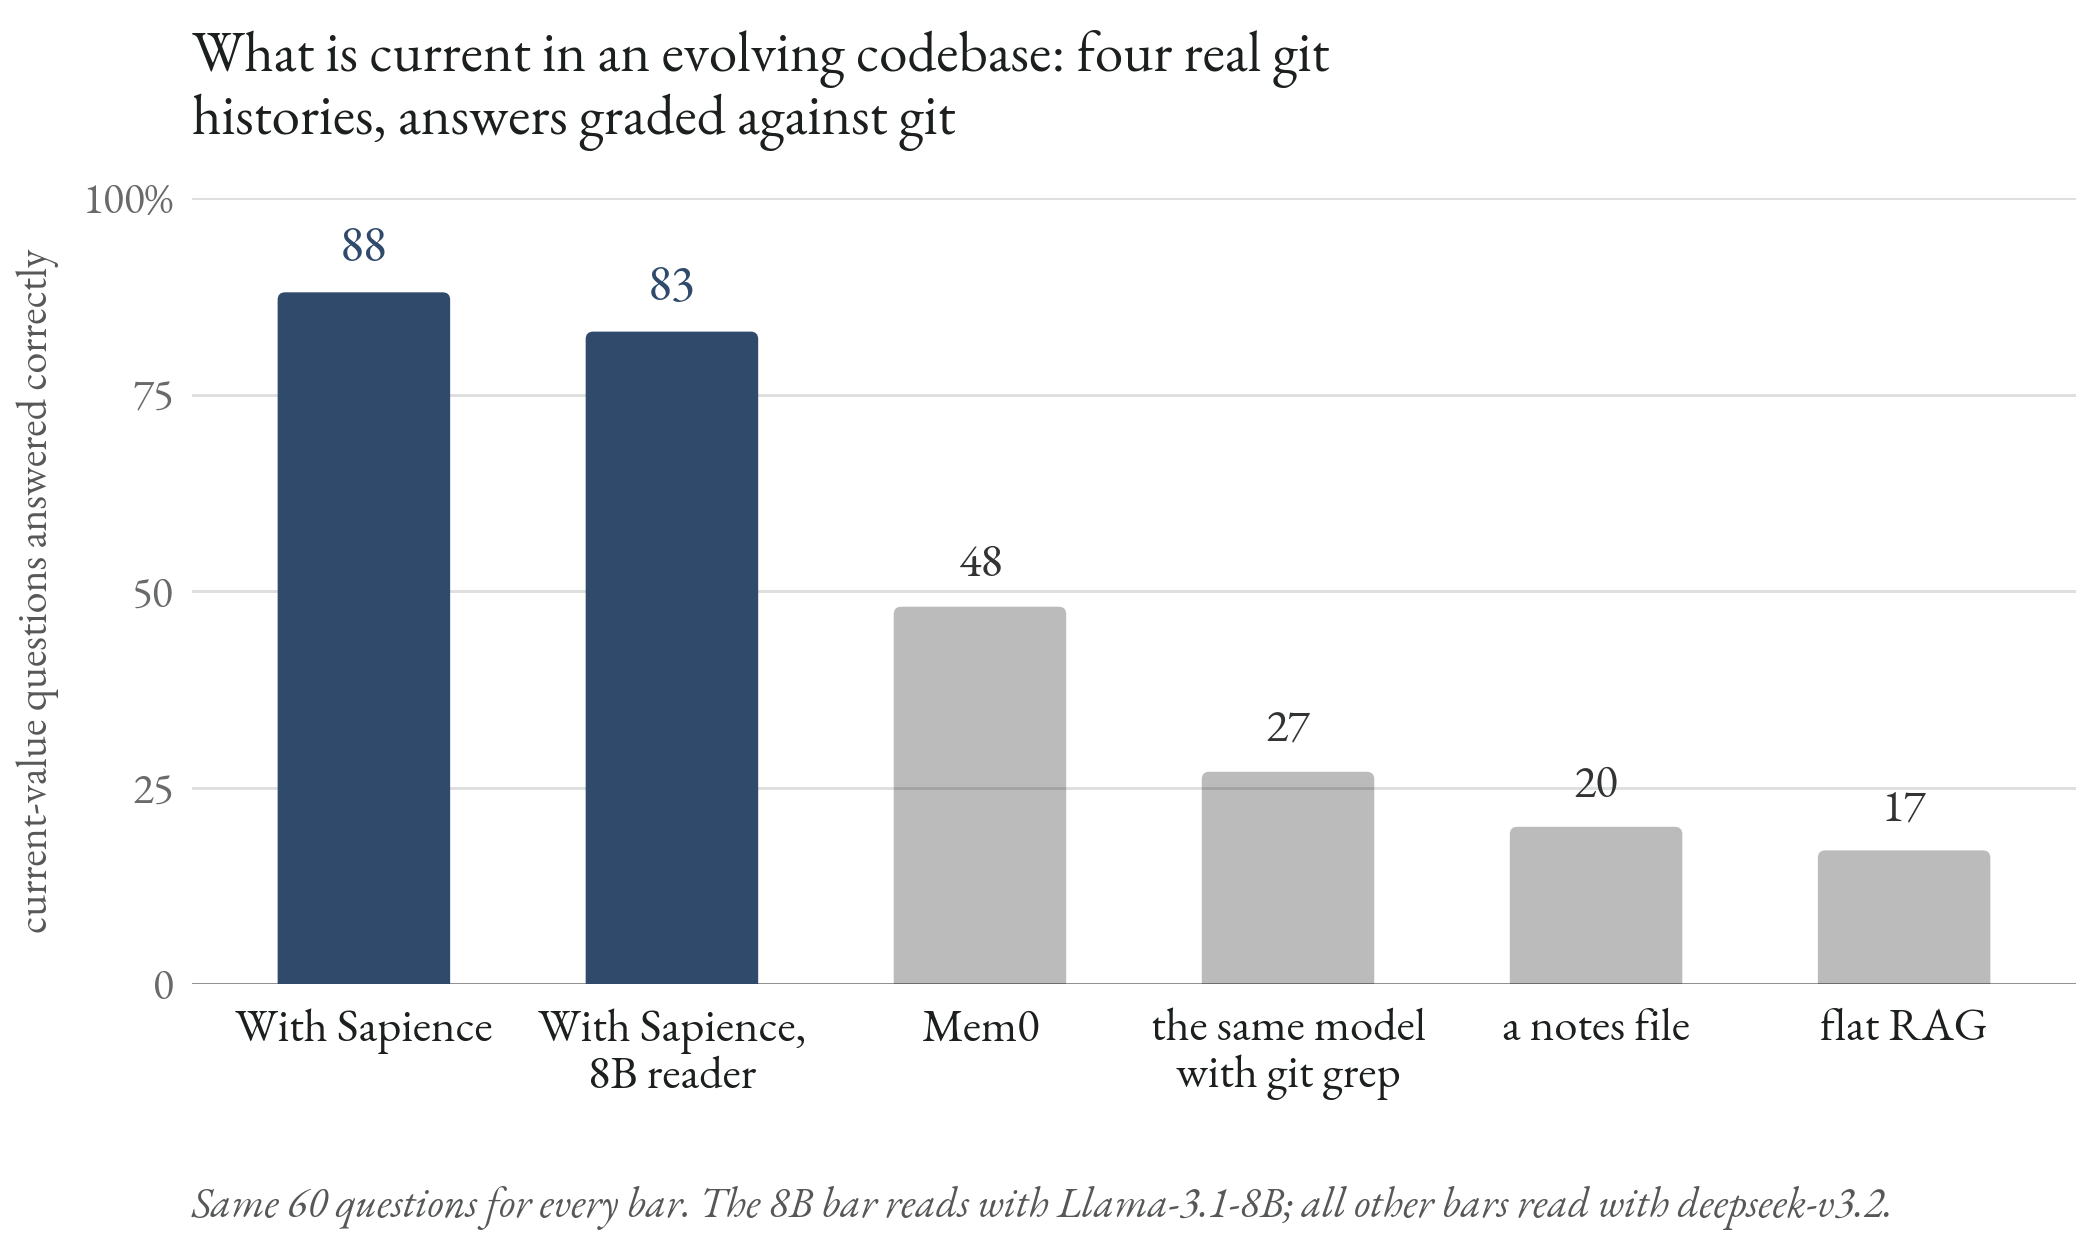
Real git histories of Django, LiteLLM, huggingface_hub and vllm, answers graded against git, no AI judge.
Works across models
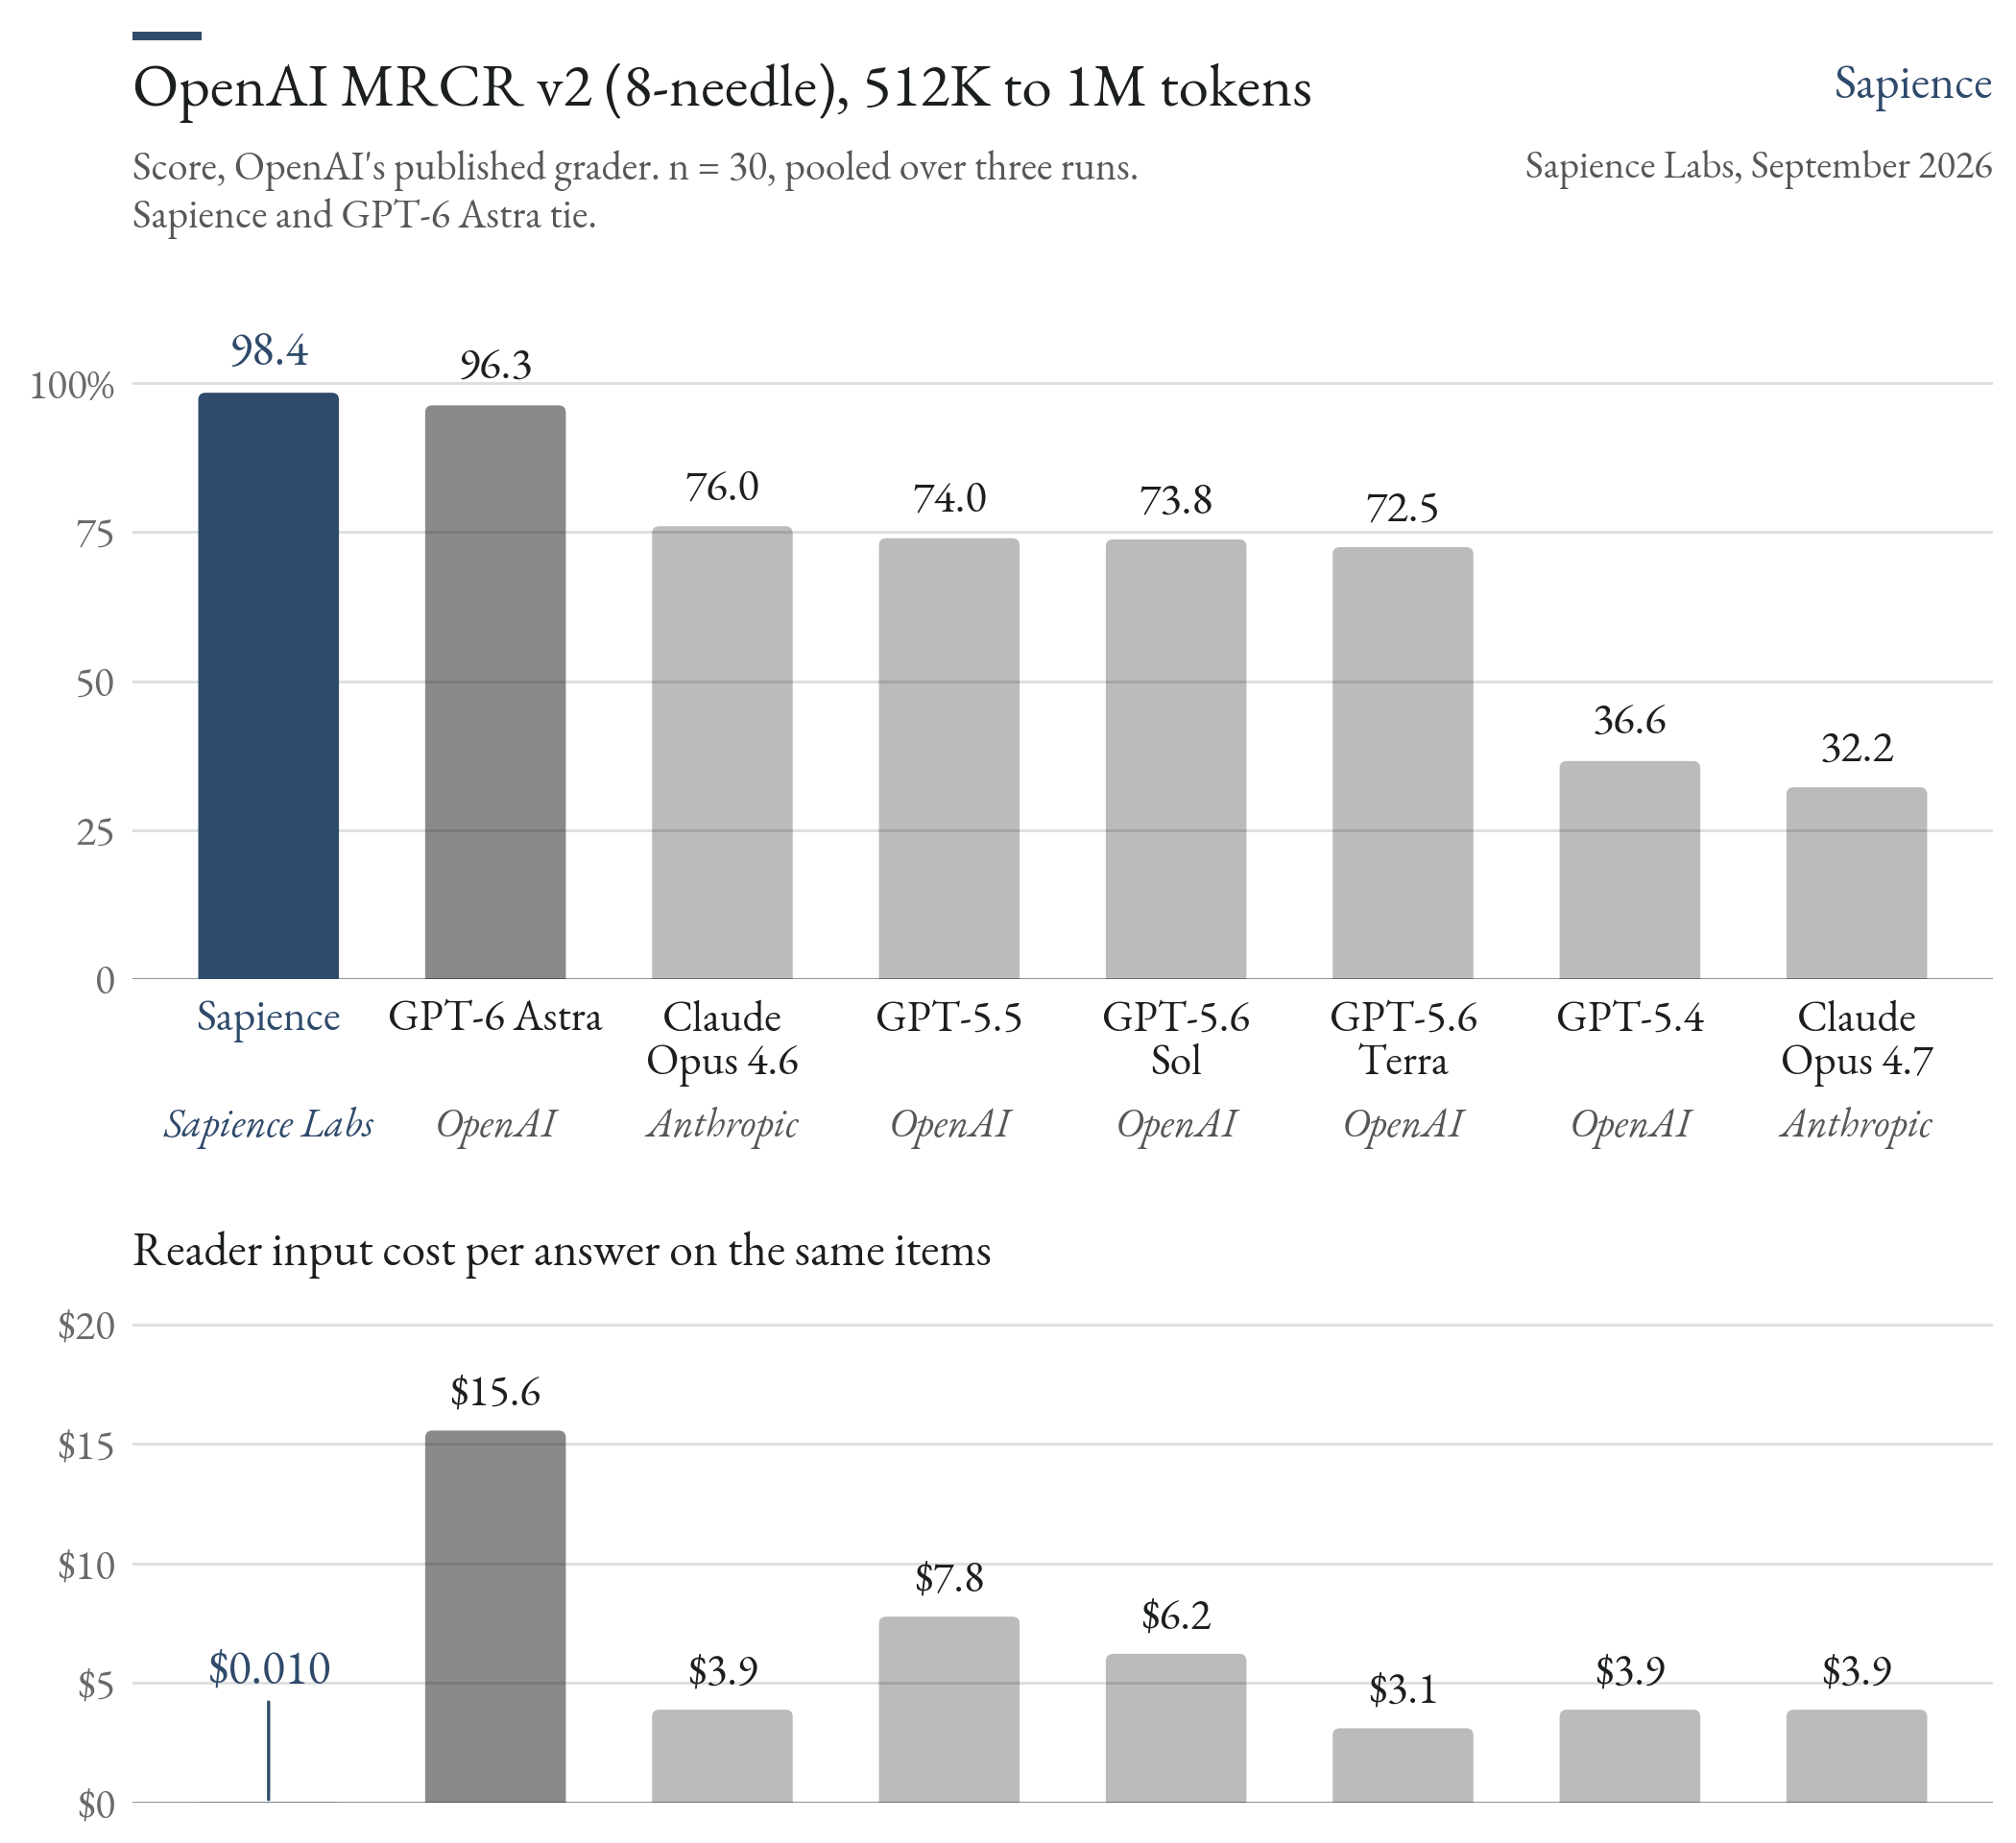
The same model scores 86 with Sapience against 20 without it. On OpenAI's own long-context test, Sapience ties GPT-6 Astra, 98.4 against 96.3, reading about fifty times fewer tokens per answer.
Scope BABILong at 128K, the same model: 86 through Sapience against 20 by the first-sentence rule; judge-scored on both sides, 86 against 65. OpenAI MRCR v2, 8-needle items of 512K to 1M tokens, against vendor-published values.
BABILong at 128K, the same model: 86 through Sapience against 20 by the first-sentence rule; judge-scored on both sides, 86 against 65. In this benchmark nothing is fine-tuned and no weights change.
Learns without forgetting
In a two-task study across seven models from 7B to 397B, Sapience forgets 4 to 18 percent of the first task instead of 50 to 94.
Scope Synthetic two-task study on seven open models from 7B to a 397B mixture of experts, 17B active; three seeds per rung.
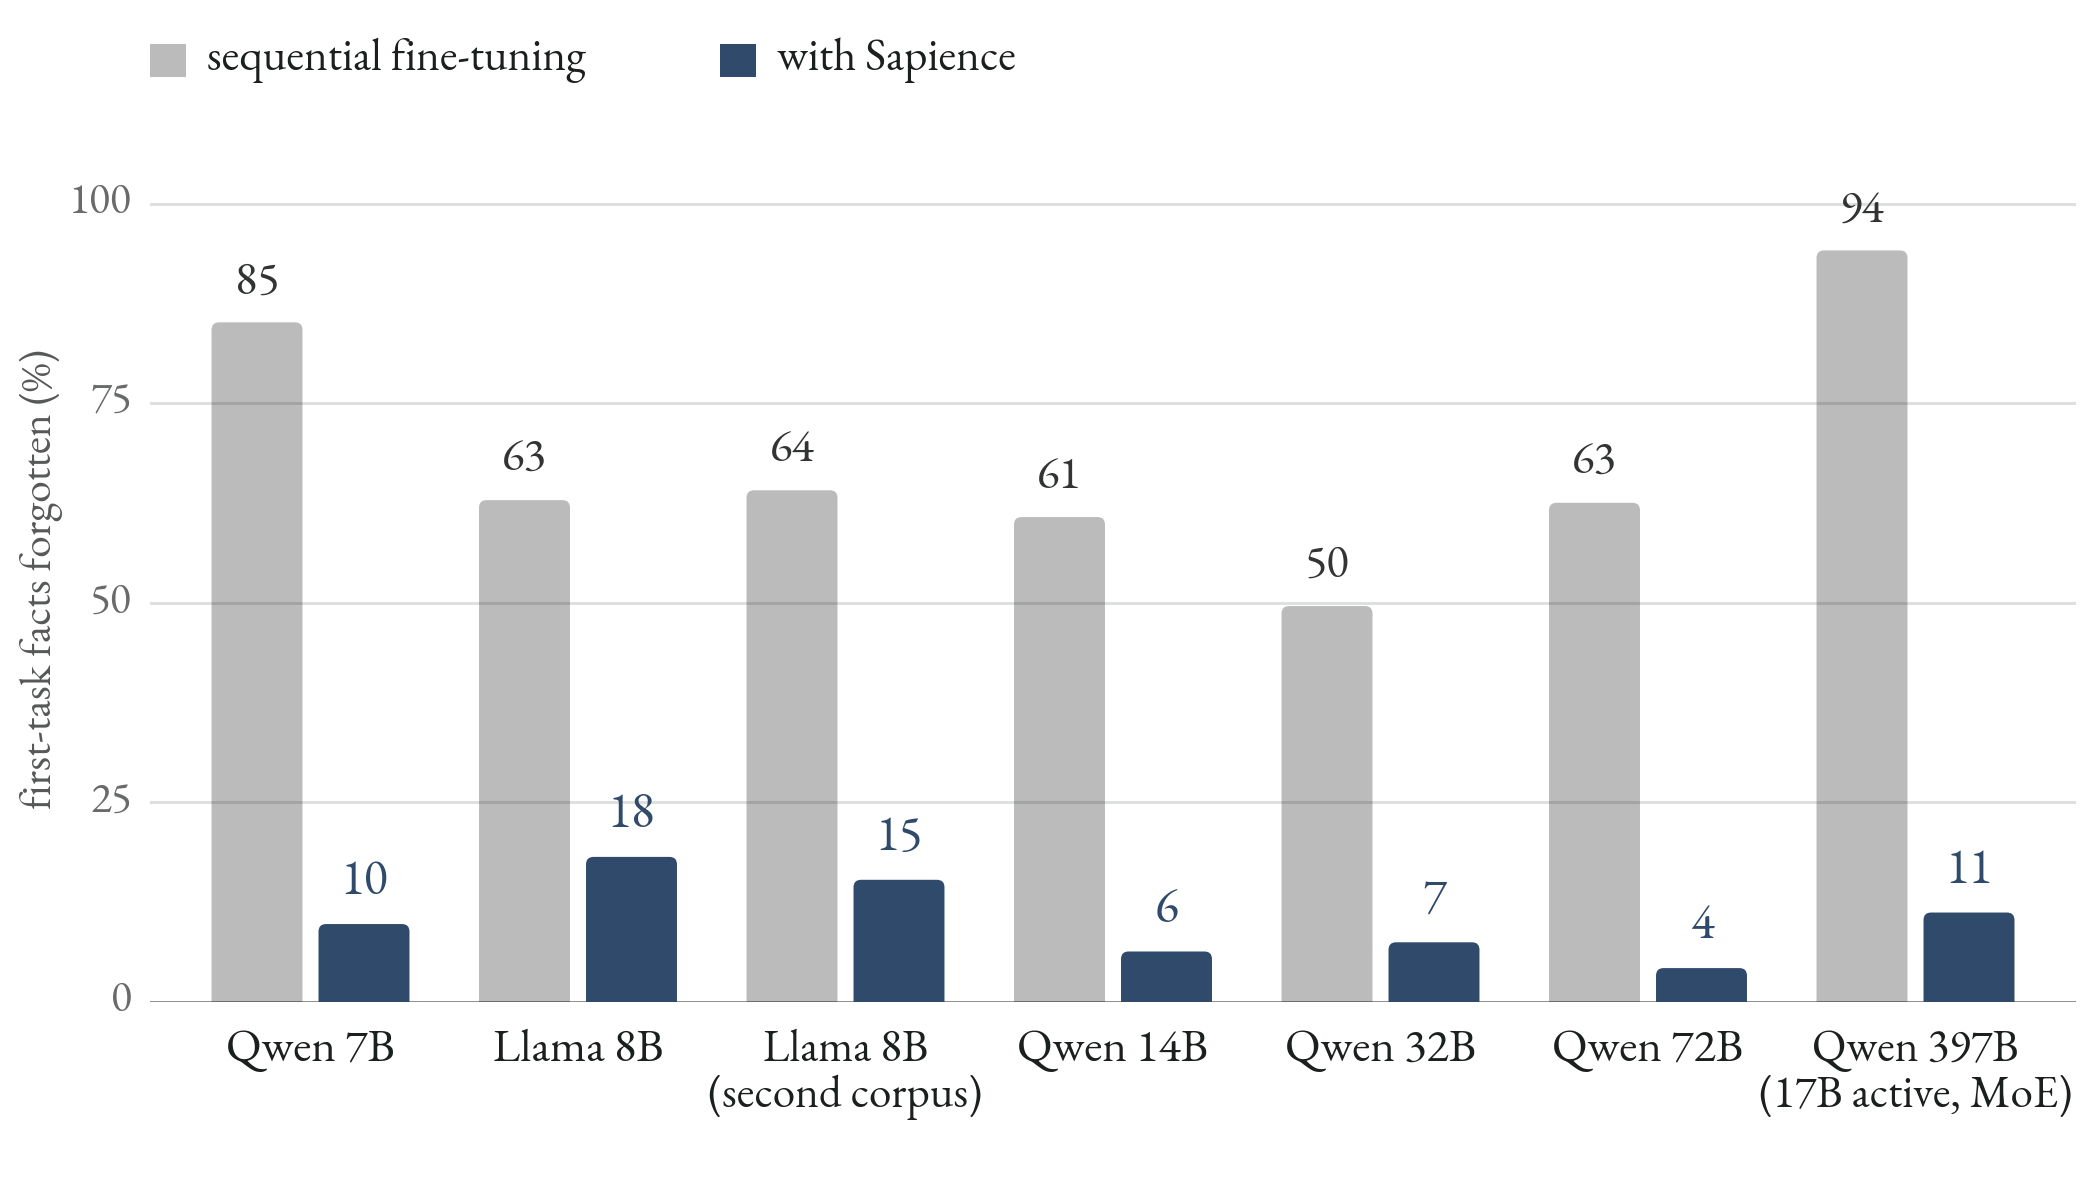
Synthetic two-task study on open models from 7B to a 397B mixture of experts; three seeds per rung; the 397B has 17B active. With Sapience the second task is learned as well or better. A model trained from its own record also answers tasks it never saw better, +6.01 points. The result is not a guarantee of perfect recall.
The method
Sapience uses an approach based on how people learn. It is built with two speeds, the way a brain is. One part captures what you establish while you work, with its source. The slower part consolidates and continues to improve while you are away: what matters is kept, and what changed is marked as changed, so newer versions take precedence over earlier ones. When you ask, your AI reads a few hundred tokens of what is current instead of your whole history, so answers stay right and cheap as the record grows.
The model underneath is a part you can swap, and each person’s model keeps training on their own work every day. The theory is complementary learning systems, and the results are under Research.
The app
A pre-trained model is trained on information up to a cutoff and then stops learning. The memory other assistants offer is a short list of preferences and details kept inside one product, with no sources and no sharing, so you still explain your project and its constraints again. Sapience keeps learning from all your work, including what you do in other AIs.
The live app, not a mockup, recorded at phone size. The lab is invented, and the waits for the model are shortened.
More of what it does, and who it is for
A living map. Your work organizes itself into a navigable map, from a single thought to the whole of what you know.
Quietly, in the background. It works behind your Claude, GPT, Cursor, or Codex sessions over MCP, reading what you know and writing back what you learn. Reading the few objects that matter instead of your whole history, answers arrive at roughly 1,800x fewer tokens per query once your accumulated work passes a million tokens (a read scales with the question rather than your whole history; on our benchmark corpus). Your plan does more before it runs out, because your AI reads three facts instead of replaying your history.
Your sessions talk to each other. A session can leave an addressed note for another thread, or a future you. Pinned commitments surface when the next session starts, and results return to the thread that asked, across Claude Code, claude.ai, Cursor, GPT, and Codex.
One AI can hold the whole problem. Agent swarms split a problem because one context cannot hold it, and the handoffs between agents lose constraints and drift goals. Sapience keeps what you have established outside the window and brings back only what an answer needs, so the problem never has to be split. Agents become optional workers you add when you want them. Goals hold: the whole problem stays in one mind across long work. Objectives do not quietly drift out from under you.
Three kinds of work it is built for. Research: keep a project’s findings with their sources, and the reasoning behind each decision, across the AIs you work in. Knowledge work: a product lead, consultant or writer keeps a project’s decisions straight across Claude, ChatGPT and the rest. Working together: two people, each on their own AI, plan a trip or a side project, and one AI can use the notes the other person chose to share, with their name on them.
The first time a colleague’s knowledge lights up against yours, the network’s purpose becomes clear.
“It’s amazing to have one brain’s memory infuse all my sessions: my Claude Code and web sessions are fully aware of each other now, and they talk to my Codex sessions too, across providers. That brain is constantly compounding, and it augments my own: it proactively suggests new ideas and connections.”
“This is something incredibly useful. The cross-domain connections are things I would never have found on my own.”
“This is very promising. Having the exact paper referenced is crucial. You know it’s the right thing, not something outdated.”
“Having a 2nd brain that is systematic and can help me keep hold of all the loose strings associated with my work is definitely invaluable.”
“The more collaboration across the world, the faster science progresses. I one billion percent see the benefit.”
A handful of researchers run Sapience in their daily work.
Sapience Labs
Knowledge back with the people who produce it, and moving between them again.
Collaborative superintelligence, as we use the term, is people and their AIs learning from each other, with each contribution credited to the person who made it.
Every AI today learns once and serves one person at a time. Sapience learns continuously from your work and with the people you choose. It provides continual learning at the system level: it never stops learning from your work, and nothing leaves your control. Its unit is the Knowledge Object, one claim reasoned through once, carrying its type, its source, and its edges to the claims around it.
Open standard, sealed engine. The Knowledge Object is an open standard: signed, credited, typed and readable alongside the open formats that already exist. We keep the intelligence that finds the connections for ourselves. CoreTx stewards the standard in the open.
Sapience uses a complementary-learning architecture, with seven patent families filed across it. We are validating performance against the strongest pre-trained baselines and report those numbers separately. All results, with figures, are under Research.
Sapience Labs is a team of scientists and engineers from Google DeepMind, Meta, SpaceX, Harvard, Cambridge, Berkeley and UChicago who have together raised $100M+ for previous ventures. If you want to work on this problem, join the team.
Sapience works with existing laboratories. We start with individual researchers. The intended path runs from individuals to organizations, and then to discovery partnerships. For backing or partnerships, write to Oliver Zahn at oliver@coretx.ai.
Attention appeared in 2014, in an academic lab. The protein-folding breakthrough built on it came six years later, somewhere else entirely. The intelligence existed. The connection was the bottleneck.
Why connection, and why people
An enclosure of knowledge is underway: the big labs bake expert work into private weights and rent it back. What matters next lives in experts' heads and private work, on the order of a million times larger than the web (Trask and Strahm, Institute for Progress, 2025).
Under current arrangements, each scientist is several times more productive while their fields are measurably less connected (Nature, 2026). Much of AI-for-science aims to automate discovery and remove people from the process. Sapience’s discovery process depends on people. Each person decides what to share and recognizes a complementary contribution. What each person learns makes the next person faster.
Essays, the open standard, and a map of agent memory architectures
Essays in sequence (the argument, in order):
Open
Ours
Every architecture announced this year falls into the first two categories: in context or in weights.
In context
improves one model’s performance
System-level learning
lets new knowledge build on what you have already established
In weights
improves one model’s performance
One minute with an invite code. It reaches you in claude.ai, ChatGPT, Cursor, Claude Code or Codex. No code yet? Ask for a place.
One command installs it in about ten minutes, with no API key. It runs behind your Claude Code, claude.ai, Cursor, Cowork, and Codex sessions, which share one Sapience across every session and interface, and starts learning from them. Each session knows what previous sessions learned, whichever tool you use.
What are you working on? One line is enough.
You are on the list. We will send your invite code by email.
Prefer email? feedback@spnc.ai
Privacy
We keep only the knowledge objects we extract, never your raw conversations, and your data is never used to train anyone else's model.
Your link is private and unguessable, and nothing auto-deletes: your Sapience stays until you delete it, hosted or on your own machine. For a fully private or on-prem deployment, talk to us.
Installing, and live sync with your AI
Ask for a place and we send an invite code. The build takes about ten minutes: no setup, no API key, one line builds your Sapience from your recent work and gives you a private link. The first discoveries are theirs. Come for the independence. Stay for the network.
$ curl -sL "https://spnc.ai/install?i=YOUR-CODE" | bashyour code arrives with your invite · read on your laptop, never uploaded
Once your code arrives: Mac and Python 3, your history is read locally, the asking and connecting run on us. Not a terminal person? There is a one-click Mac installer. Prefer to see one first? Ask the live example your own question.
Live sync with your AI
Connect over MCP and the loop closes: your AI reads what you know mid-conversation and writes what you learn back, so every session starts smarter than the last.
The four tools your AI gains
search (query) // find it in your knowledgeload_context (topic) // start the session smarterremember (insight) // signed to youask (question) // a cited answerPeople learn individually and can do more by connecting what they know.
Sapience turns what we each know into what none of us could know alone. Read the declaration ›